Showing posts with label LLM. Show all posts

Tuesday, June 2, 2026

LLM Pipelines

June 02, 2026 0

We can incoporate 3 ways of LLM through pipelines:

1) DAG workflow
a) Pre designed prompts + code paths
b) Modular components [Yes or No prompts]
2) Agents
LLM setups to make their own decision
3) Agentic workflows
Hybrid architecture


We can create a work flow through LangChain and LangGraph.

LangChain:
It is designed for LLMs. It can be useful for custom workflows, tool integration and agent collaboration. 
LangGraph:
LangGraph library used for build a stateful, multi actors with LLMs

LangGraph concepts:
State: a TypeDict that flow through graph and updated by each nodes.
Nodes : Python function used to receive update and return updates
Edges : Connection between Nodes
Reducter : control how state updates combine with over write or accumalation


Retrieval Augmented Generation (RAG)
A RAG is an interactive system (chatbot) that combined a retrieval (static content) with a dynamic conversation generator.

Components of RAG:
An index : A mechanism to convert a raw data into Vector database
A retriever: Closed tied to the index and retrieve a data from database based on query
A generator : an LLM to reason a through user query and the retrieval knowledge to provide an inline conversational response.

Sementic search:
A system has understand of context and meaning of user query and matches against the available document for retrieval. It can find relevant document without having to rely on exact words or n-gram matching. It often uses a pre-trained large language model to understand the nuance of the query and the documents.
We often use of cosine similarity to define a raw data that produce in vector database.
Cosine is bounded between 1 and -1.
smaller angle == Cosine [up]
larger angle == Cosine [down]
Perpendicular == Cosine 0


Dense Model:
A dense model uses all the parameter for every tokenized. It would be better for semantic similarity, paraphrases and conceptual queries. [Example GPT3 & GPT4 are using Dense model]
Pros:
* Easier for training the model
* Simple architecture
Cons:
* high computation cost
Sparse Model:
A sparse model is used for small set of parameter for each token. The most common Sparse architecture is Mixure of Experts.
Pros:
* Less computation cost
* Better scaling efficiency
Cons:
* Potential training
* More complex architecture


Cross Encoders:
A cross Encoder is a non-generative LLM specifically designed to take in two inputs separated by a special token and return a single output.[Ex. BERT]

Reasoning LLMs:
Reasoning models like Deepseeks R1, OpenAI are orginal "o" series and Anthropic's Claude/Opus 4 models are autoregressive LLMs that have been trained to give a discursive chain-of-thought reasoning step before giving a user response.
For example, the Claude 4 series of LLMs provide separate reasoning tokens alongside the messages to the user, as is common with most frontier reasoning LLMs.


Agents:
1) Solo Agents
2) Supervisor + specialist agent


Monday, April 6, 2026

Optimizing AI models for Production Environment

April 06, 2026 0


We can LLMs in three ways by usually

1. Encode text into semantic vectors with little/no file tuning
2. Fine tune a pre-trained LLM to perform a very specific task using by Transfer Learning
3. Query an LLM to solve a task which was pre-trained or could intuit.
Two types of LLMs now.
1) Auto encoding LLMs - Learn a entire sequence by predicting tokens (words) given past and future context.   It is best for classification and embedding + retrieval tasks. [Example BERT]
2) Auto regressive LLMs : It will predict a future token 
LLMs excel at task that require reasoning using context and input information in the conjunction to produce a nuanced answer.


AI agents are semi autonomous systems that interact with environment, make decisions and perform tasks on behalf of users.
Autonomy - They can perform tasks without continuous human intervention.
Decision Making - Use data to analyze and choose actions
Adaptability - Learn and improve over time with feedback.
Optimizing Models:
Speculative Decode : Using an assistant model to guide next token perdition
Caching OS models : Implementing prompt caching with open Source models
Quantization : Reducing computation requirement of neural network.
Distillation : Transfer knowledge from large model into small through targeted fine tuning.
Speculative Decoding:
Assistant agent calls for forward method of calling [calling parameter over and over again].  The main model simply verifies which token is agreed with request.


Sunday, March 22, 2026

LLM Context management along with Cursor 2.0

March 22, 2026 0


Cursor 2.0 is an AI editor for Production Environment. It will be run 8 parallel agents without any issue. 

Context Management like telling story when it getting convoluted. It will direct path when AI get confused.

Context window is a windows chat where user and AI interact each other.


AI driven project initialization:

1) Describe - Describe your problem or expectation
2) Define - Stack, database, auth & deployment
3) Generate - Cursor will take care of codes


Tuesday, March 10, 2026

Infrastructure as Code through AI workloads

March 10, 2026 0


A Kubernetes operator is a specialized controller designed to extend Kubernetes API, enabling the management of complex application through declarative configurations.
Kubernetes Operator operate within continuous reconciliation loop. This cycle begins when user create a resource, It prompting controller to monitoring a change and take a necessary action to ensure a desire state. Operator allow user to defined a desired state of application in custom resources, while operator
controller continue reconcile the actual state with this desire state, embodying the operational expertise of human site reliability engineer.
KubeFlow : It is a primary of orchestration tool for MI workflow. It is focus on training aspect of models.

Most using of Kubernetes resources in the real time.
APIService
ClusterRole
ClusterRoldBinding
ConfigMap
CronJob
CSIDriver
CSINode
DaemonSet
Deployment
EphemeralContainers
HorizontalPodAutoscalar
Ingress
IngressClass
Job
Namespace
Node
PersistVolume
Pod
PodDisruptionBudget
PodTemplate
ReplicatSet
ResourceQuota
Role
RoleBinding
Secret
Service
ServiceAccount
StatefulSet
StorageClass
VolumeAttachment
Binding
CertificateSigningRequest
ComponentStatus
ControllerRevision
CustomResourceDef
Endpoints
EndpointSlice
LeaseReplicationController
LimitRange
LocalSubjectAccess
MutatingWebhookConfiguration
NetworkPolicy
PodSecurityPolicy
PriorityClass
RuntimeClass
SelfSubjectAccess
SelfSubjectRules
SubjectAccessReview
TokenReview
ValidatingWebhook


Saturday, November 8, 2025

MCP - Model Context Protocol

November 08, 2025 0


MCP - Model Context Protocol:

MCP defined a LLM to access an external data, tools and context in a a structure way. MCP (Model Context Protocol) is an open-source standard for connecting AI applications to external systems and data.

Overview of MCP:

AI application such as Claude or chatGPT can connect to data sources, tools [search engine] and workflow [prompts] through MCP and perform a tasks.

MCP like an interface which communicated to MCP client and discover their requirement and offer available services for their requirement. 
MCP Framework:
  • MCP SDK - It is a foundation for all the MCP development. It will use for Production and standard projects. It can be integrate into any tools or transport (STDIO, SSE)
  • FASTMCP 1.0 - It became a legacy support and integrated into MCP python SDK.
  • FASTMCP 2.0 - This is a latest and modern feature tools kits for advanced MCP workflows.
  • Others Frameworks - Java SDK and third party libs in other languages.
Agent workflows inside of Memory:


RAG - Retrieval Augmented Generation
It converts a data into numerical representation where each piece of data has information about how it relates to others.
Retrieval - when user ask a question or search, RAG turns question or search into own numerical representation (Embedding) and find a data which is similar meanings.
Augmentation - The top search result are then added into prompt and send to back to LLM
Generation - The search results give the LLM some local context and consider as response.
Embedding:
Embedding represent text as set of numerical data along with tensors (different dimensions)
Each dimension will store some information about text meaning or syntactical meaning.
Each words or sentence with similar meaning are stored near by vector space.
Models will learn to place a similar words or sentences close  together in the embedded space.
Common pre-trained models such as BERT and RoBERTs are  used for generating an embedding inside of vector space.
We can able to use an embedded for NLP tasks like semantic search, text classification and sentimental analysis.
Agentic RAG:
It is integrate an AI agents to enhance the RAG approach. It will breakdown from complex queries into manageable parts and using API tools where need to augment processing and better result.


Implementation of AI agent

November 08, 2025 0


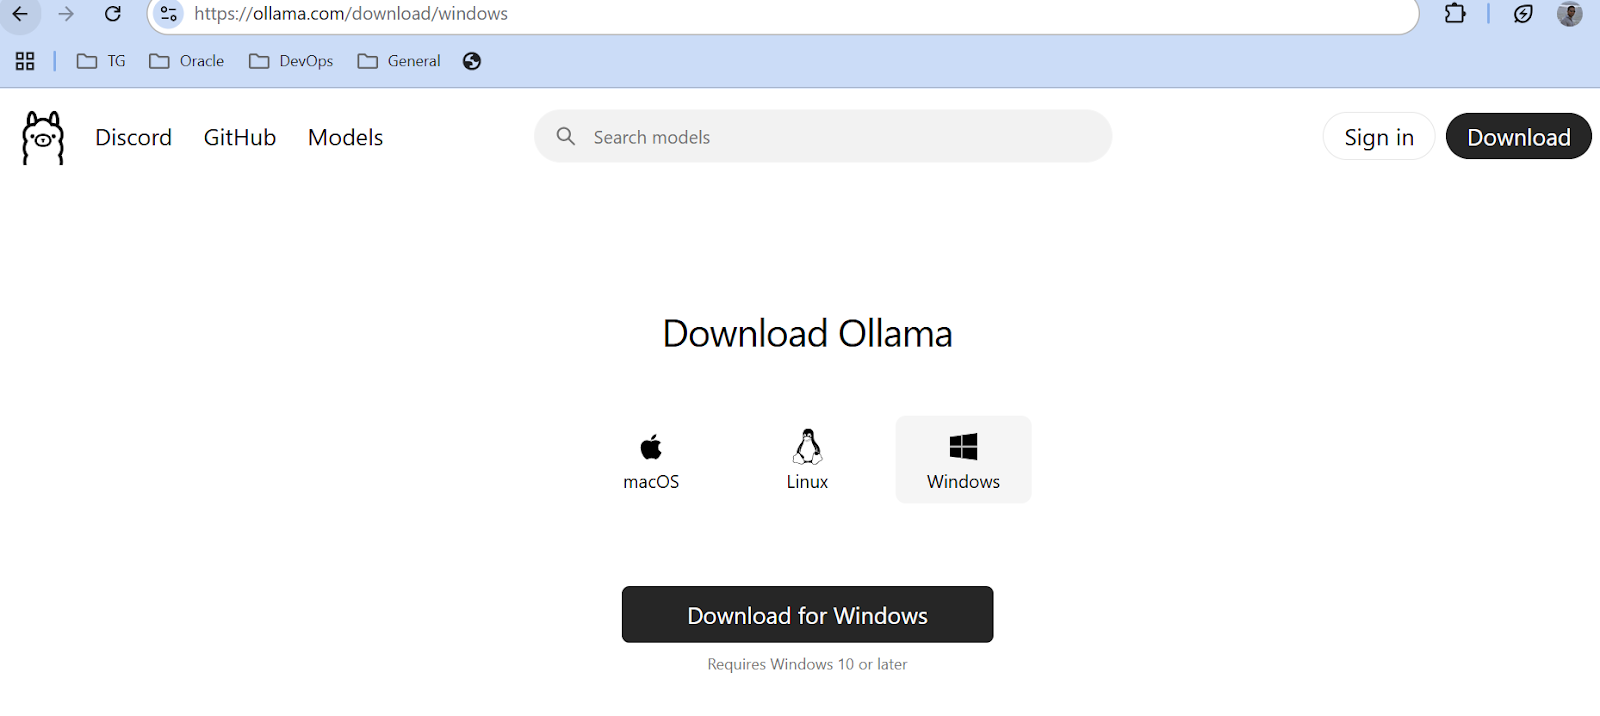
Installation of Ollama:
Ollama is an open source tool which will helps us to run a NLP [Natural Language Processing] through locally.
Step1) Downloading the Ollawa tool for your suitable operating system and installed it.


Friday, March 28, 2025

Large Language Model [LLM] - Introduction

March 28, 2025 0


LLM stands for Large Language Model. It is specifically a deep learning model, trained on massive amounts of text data to understand and generate human language, enabling tasks like text generation, translation. It often sing "Transformer" models which are neural networks that can process relationships within language.


Reasoning LLMs


Traditional LLM workflow


Traditional LLM model is refine a dataset into pretraining workflow. The pretraining send a data into fine tuning model and give a precise collected output data. It will send it to human feed back and correct incase of any mismatch with fine tuning model.

Traditional LLMs
  • Direct pattern based prediction
  • Quick but less reliable on complex tasks
  • No explicit reasoning steps

Reasoning LLM:
  • Language models are designed complex and multiple set problems
  • Break down tasks into logical sub tasks.
  • Generate intermediate reasoning steps "thought processes"
Key Capabilities of Reasoning LLMs:
1) Chain-of-Thought Reasoning
        Internal dialogue approach
        step-by-step problem solving
2) Self consistency
        Verified own answers
        Revisits problematic solutions
3) Structured Outputs
        Organized reasoning steps

Practical Applications of Reasoning LLMs
Data Analysis
Medical diagnostics
Complex data interpretation
Anomaly detection
Background Processing
Batch processing workflows
Overnight analysis jobs
Evaluation Tasks
LLM as judge
Quality assessment
Verification workflows
Limitation of Reasoning LLM
Performance Trade-offs
* Increased latency : extended thinking process leads to significantly longer response times
* Higher resource requirements: ofent require more computational resoures
* cost-implications: More tokens and processing time translate to higher operational costs
DeepSeek:

    DeepSeek applied supervised fine-tuning to refine the models' capabilities. This involved training on datasets containing reasoning and non-reasoning tasks. Notably, reasoning data was generated by specialized "expert models" trained for specific domains such as mathematics, programming, and logic. These expert models were developed through supervised fine-tuning on both original responses and synthetic data generated by internal models like DeepSeek-R1-Lite. The use of expert models allowed DeepSeek to generate high-quality synthetic reasoning data to enhance the primary model's performance.